AI Fundamentals | AI, DX & Security Glossary
Glossary terms in "AI Fundamentals" — practical definitions on AI, DX, and security for executives and IT teams, with diagrams.
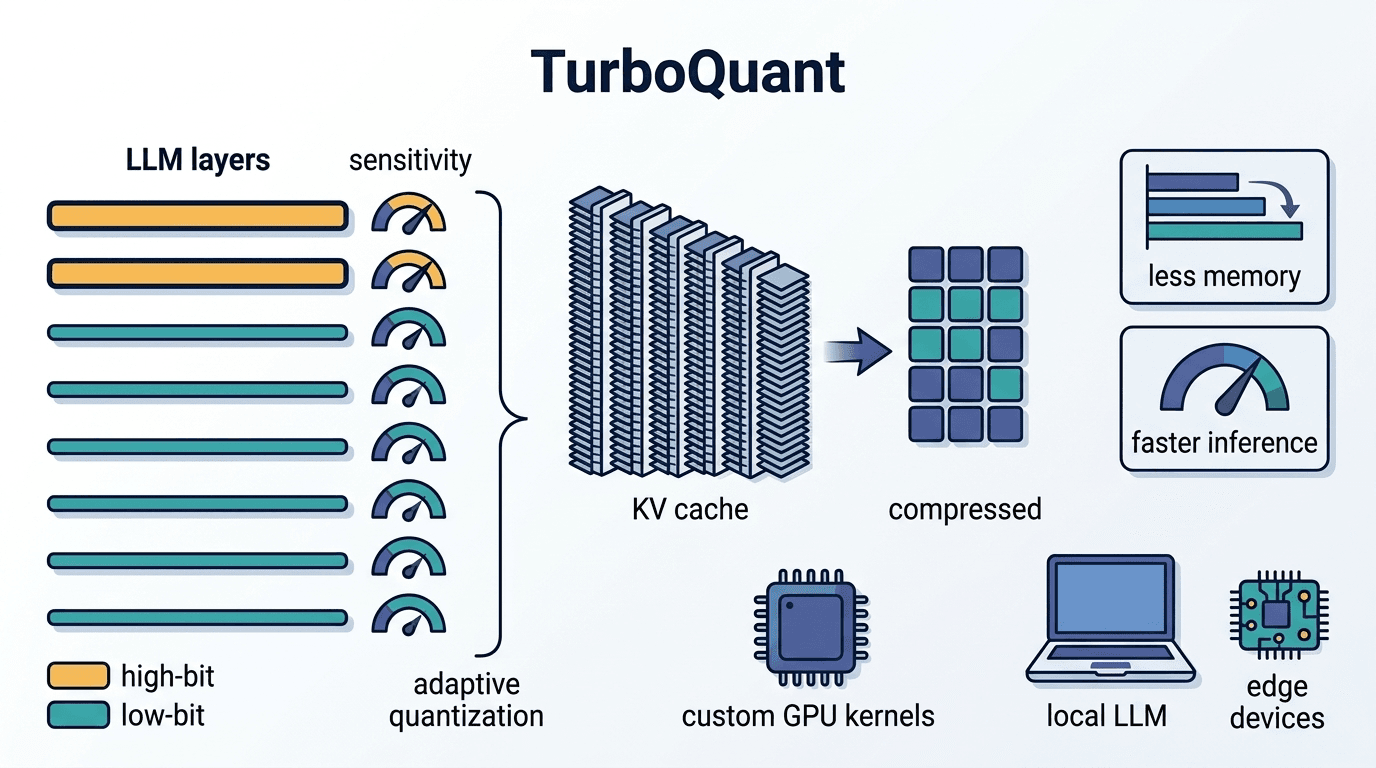
TurboQuant
A memory compression technology for LLMs developed by Google. It reduces memory consumption by up to

Knowledge Distillation (Knowledge Distillation)
A technique that transfers knowledge from a large teacher model to a small student model, creating a

Dense Model (Tightly Coupled Model)
A Dense Model is a neural network architecture in which all of the model's parameters are used for c
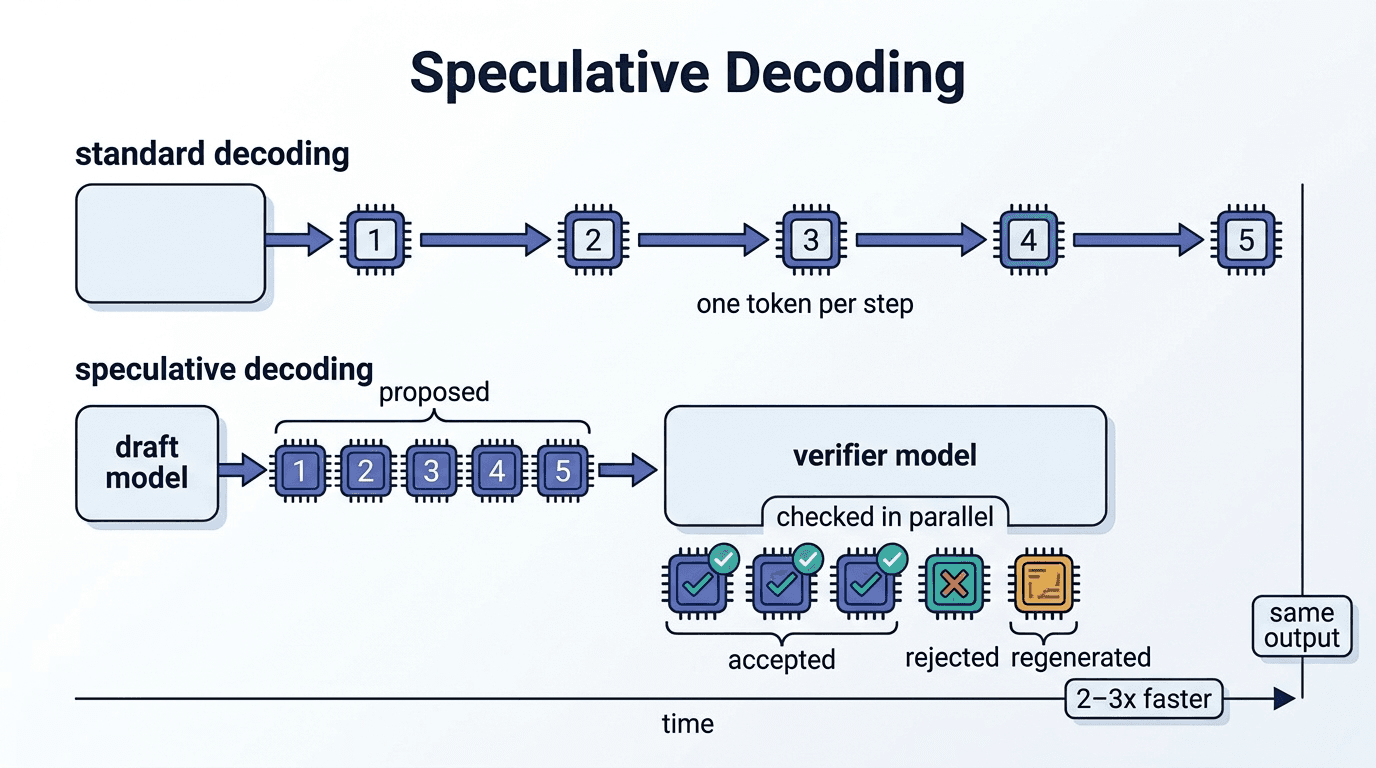
Speculative Decoding
A inference acceleration technique in which a small draft model proposes multiple tokens speculative
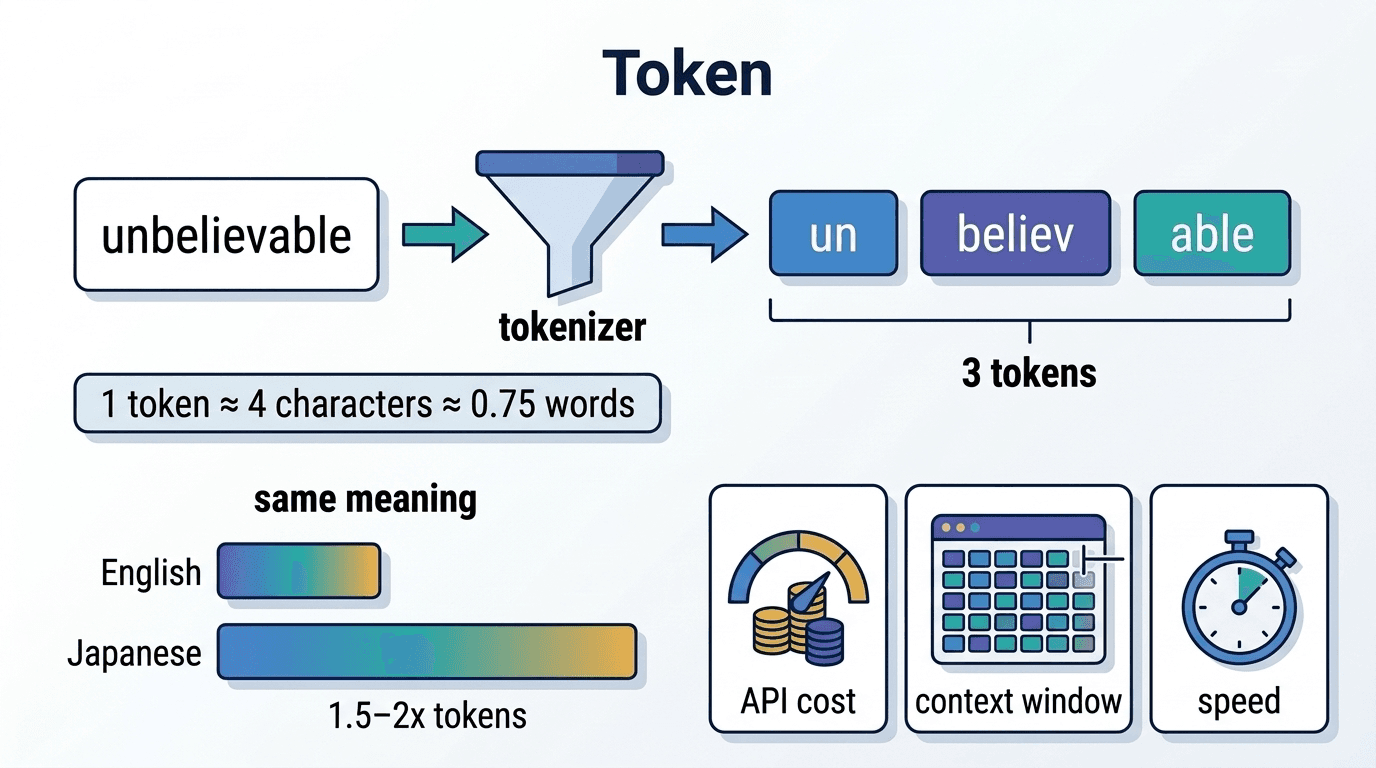
Token (Token)
A token is the smallest unit used by an LLM when processing text. It is not necessarily a whole word
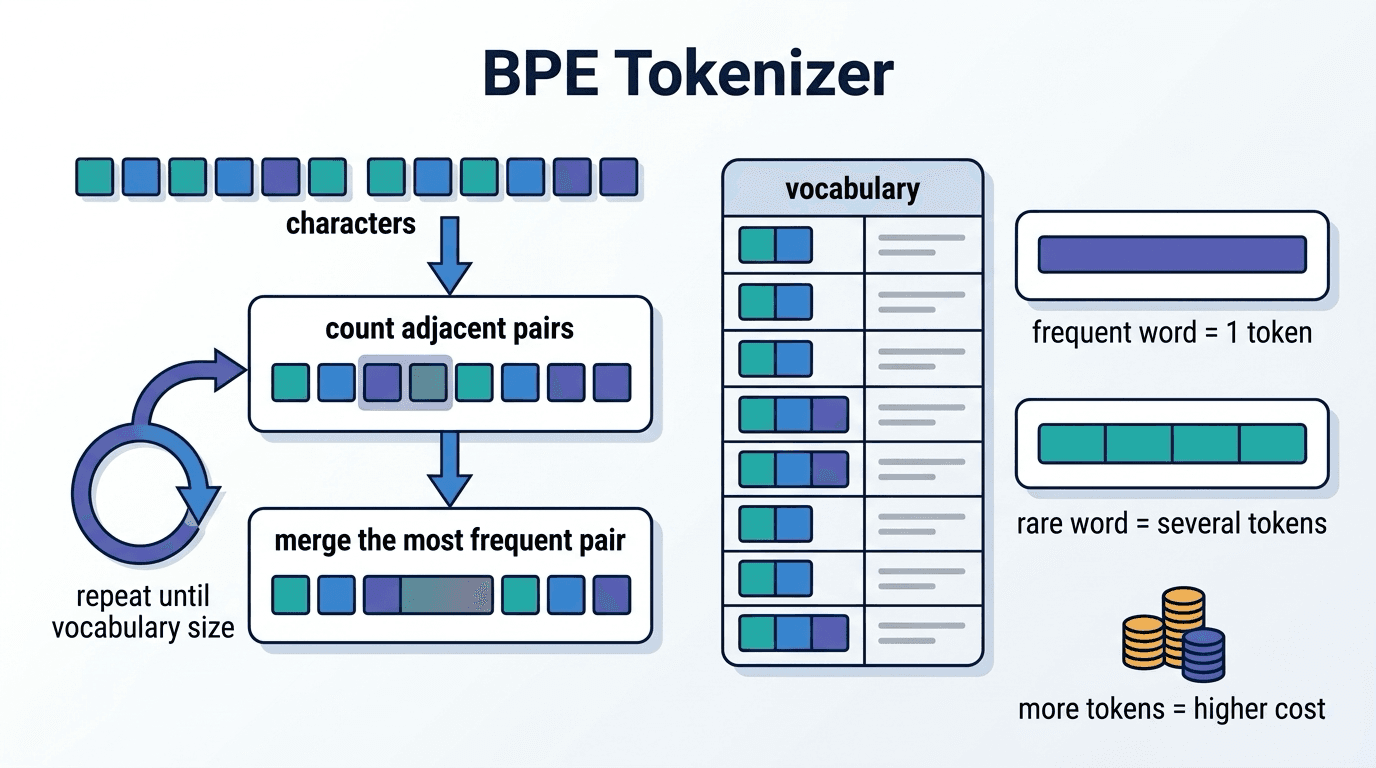
BPE Tokenizer (Byte-Pair Encoding Tokenizer)
An algorithm that merges text based on frequent patterns and splits it into subword units. It direct
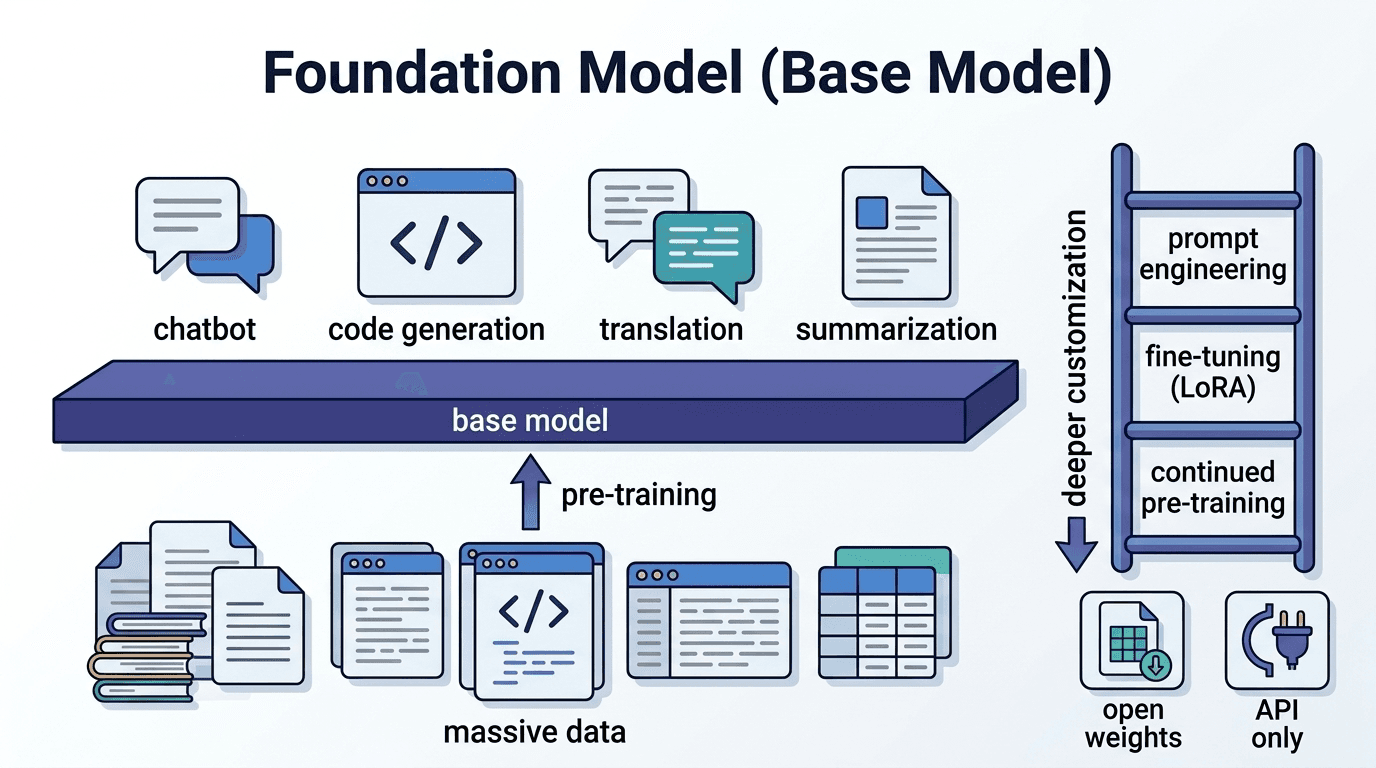
Base Model (Foundation Model)
A base model (Foundation Model) is a general-purpose AI model pre-trained on large-scale datasets. R
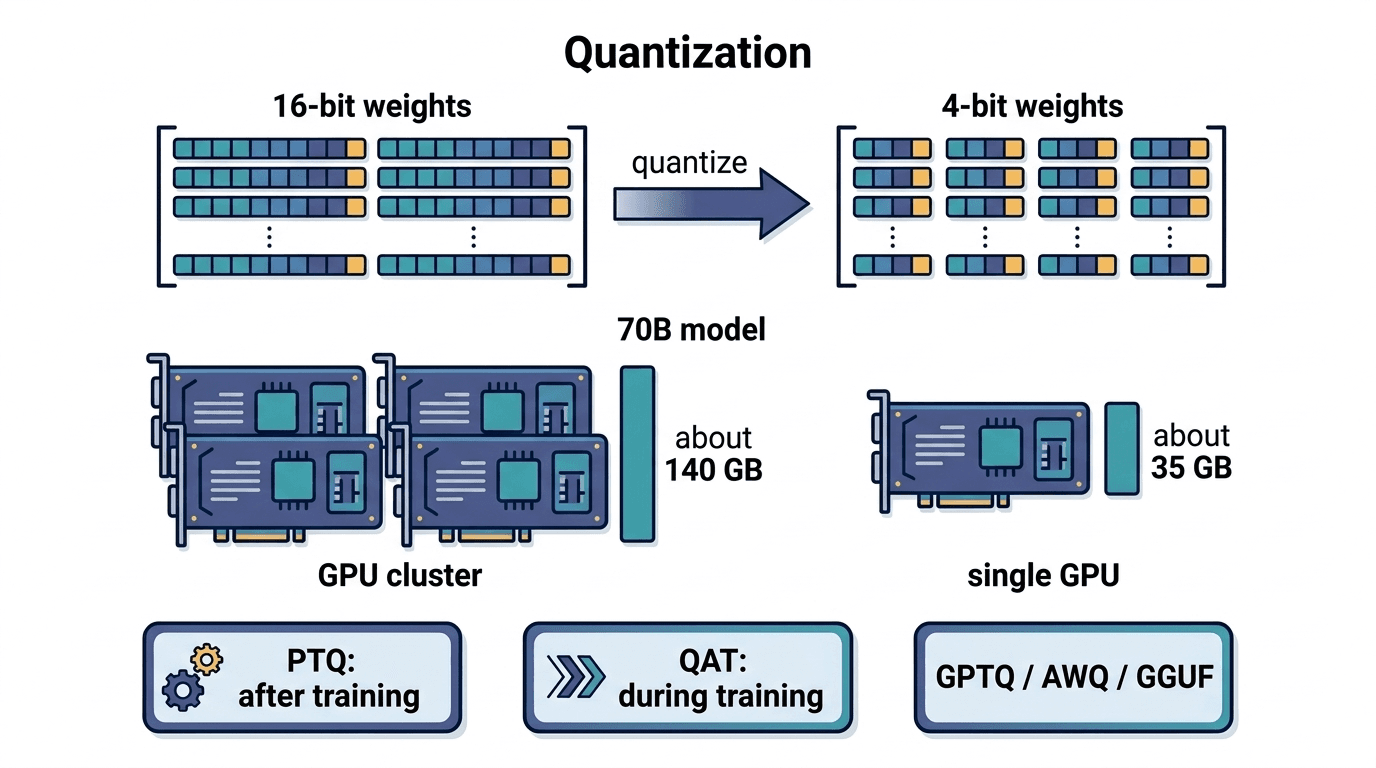
Quantization (Quantization)
An optimization technique that compresses model size by reducing parameter precision from 16-bit to
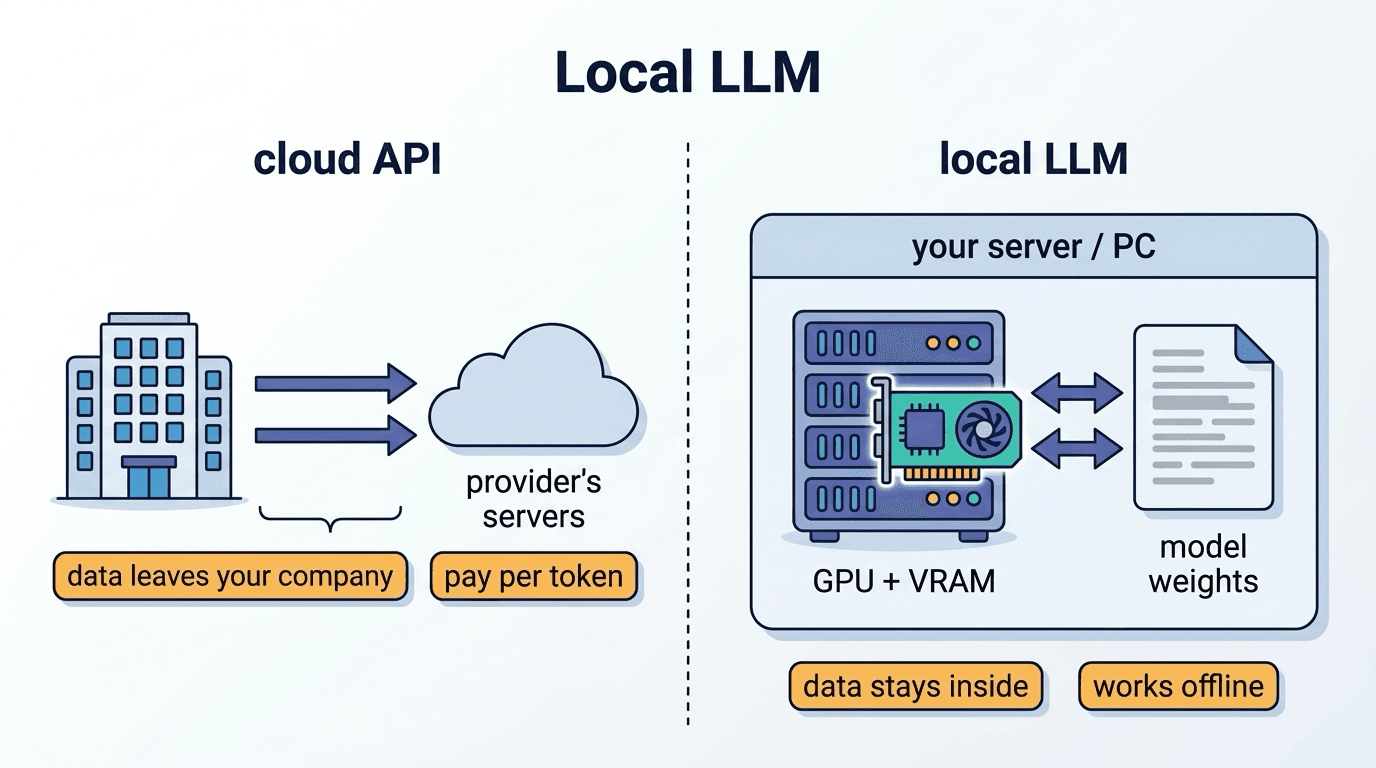
Local LLM
A local LLM refers to an operational model in which a large language model is run directly on one's
33items of 3of3