DeepSeek
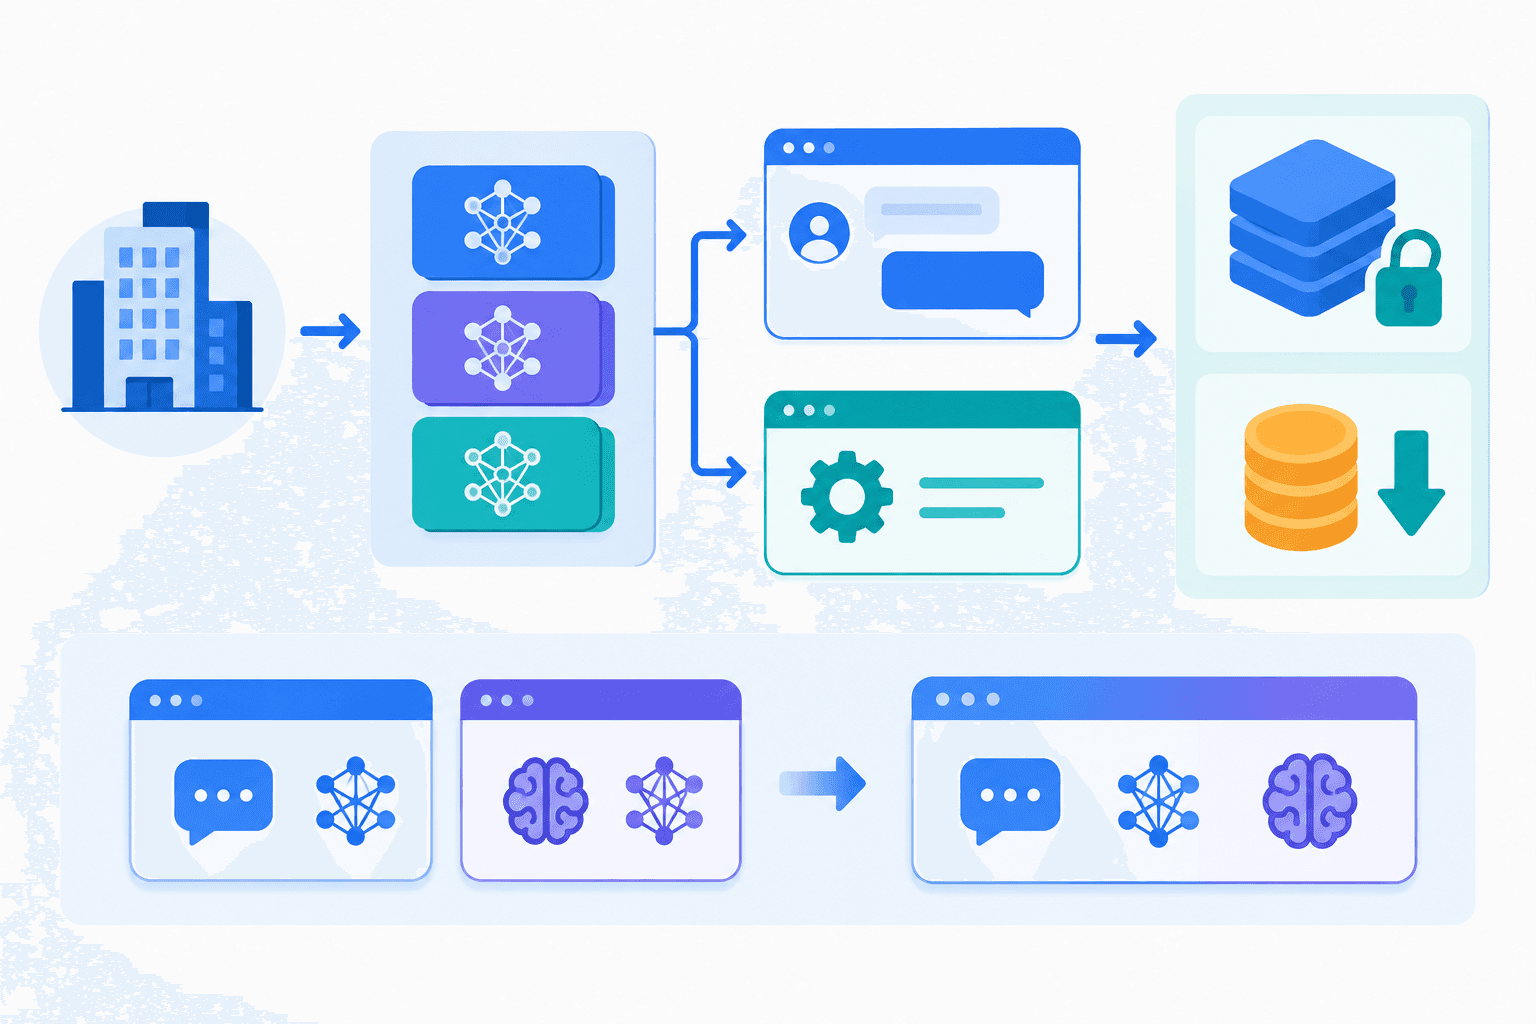
DeepSeek is a family of large language models and a chat service developed by the Chinese company DeepSeek, known for publishing its model weights (open weights) and for low inference prices.
DeepSeek is the name of a family of large language models (LLMs) and the chat service and API built on them, developed by the Chinese company DeepSeek. It is known for publishing model weights as open-weight models and for inference prices well below comparable models from other providers.
DeepSeek used to ship separate chat models and reasoning models that think step by step before answering. The latest generation combines both in a single model that can switch between "think first" and "answer immediately," and it supports long contexts for reading large documents in one pass.
Three ways to use it, and where the data goes
| Option | Where your data goes | Best for |
|---|---|---|
| Official chat (web / app) | DeepSeek's servers | Personal experimentation |
| Official API | Same as above | Apps that do not handle confidential data |
| Run the published weights in your own environment or cloud | Stays under your control | Work involving confidential data |
The API follows the OpenAI-compatible format, so existing apps can switch easily. With the weights, you can run the model on your own GPU servers or on the model-hosting services of major clouds (local LLM). Smaller distilled variants (knowledge distillation) run on relatively modest GPUs.
What companies should check
DeepSeek's privacy policy states that data entered through its official services and API is stored on servers in the People's Republic of China. Before entering personal or confidential information, check it against your internal policies and applicable laws, such as Thailand's PDPA. Note also that several countries and public bodies restrict the official app on work devices.
If data must not leave your organization, running the weights in your own environment or through a managed cloud service keeps it under your control. Answers may still be restricted or skewed on certain topics, so test with an evaluation set before relying on it.
Pricing
The chat service is free. The API is billed by input and output tokens, with discounts for cached input. The weights are free to use; self-hosting costs GPUs and operations. Prices change, so check the official pricing page.
Do not choose on price alone: compare accuracy, language quality, response speed and support on the same evaluation set before adopting a model. Our approach is described in the LLM cost optimization guide. We help with model selection and secure architecture through our AI & DX services.
Related Terms
AI Checker (AI-generated text detector)
An AI checker is a tool that estimates whether a piece of writing was generated by AI, mainly from s
AI Mode (Google AI Mode)
AI Mode is a generative AI search mode built into Google Search that answers questions conversationa

Context Window
A context window refers to the maximum number of tokens an LLM can process at one time, indicating t

Fine-tuning
Fine-tuning refers to the process of providing additional training data to a pre-trained machine lea